How Forage Works
4 min read · Last updated · Page version 21
The sequence
1. Forage reads Squirrel's record of the estate. It builds its inventory of SharePoint Online files and Squirrel-archived files from the records Squirrel already keeps, so SharePoint is not crawled a second time.
Because the inventory comes from Squirrel, Forage sees what Squirrel records and nothing else. It reads the sites on Squirrel's list of sites.
2. It reads each document, and records what happened to it. PDF, Word, Excel and PowerPoint files including templates and macro-enabled files, older Office formats, Outlook and standard email messages, OpenDocument files as LibreOffice and OpenOffice save them, the words on drawings (.dwg) saved in any version of the format from 1984 on and on exchange drawings (.dxf), and rich text, plain text, CSV, HTML and XML, without needing Microsoft Office or AutoCAD installed.
Scanned PDFs and image files are read with optical character recognition, so scanned contracts and forms become searchable. A page read with low confidence is never left out: its text is kept and made searchable, and the record of how the document was read marks that page as a low-confidence reading. Any page read this way can contain misread words.
For every document it reads, Forage records how it was read, page by page, and keeps a cryptographic fingerprint of the file.
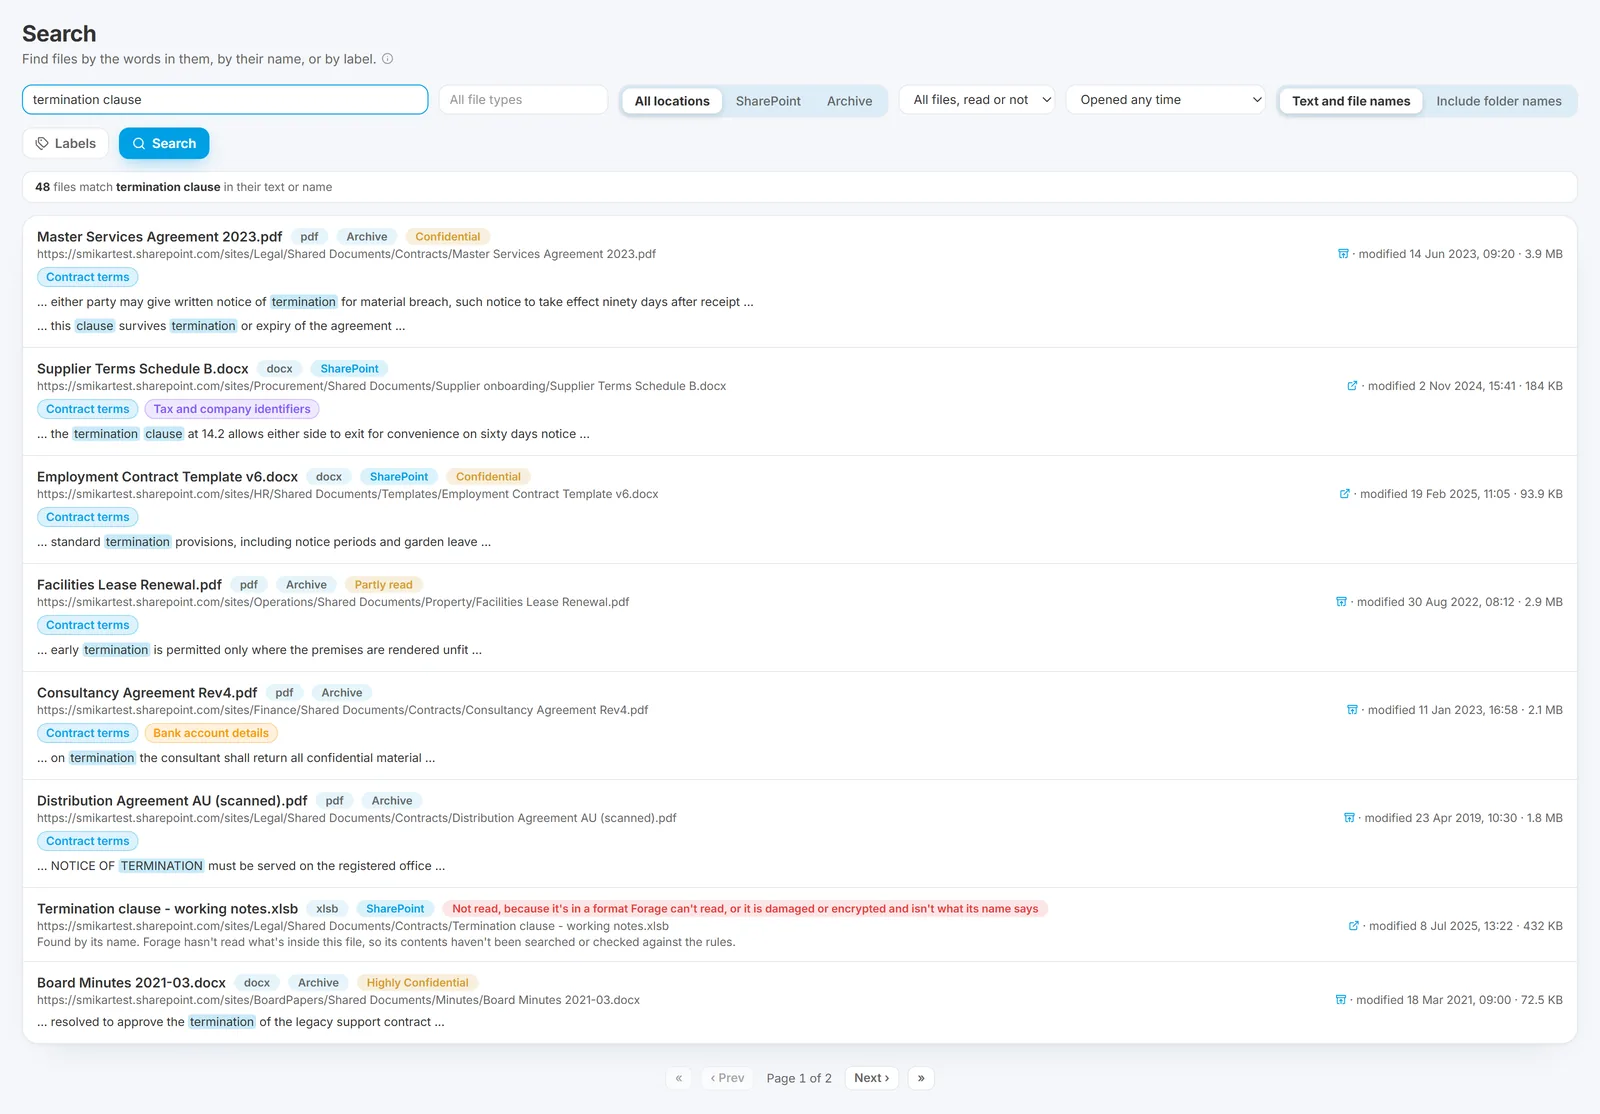
3. It keeps a searchable index inside your own deployment. One full-text search across live and archived content, with highlighted extracts and filters by source and document type.
4. Where content classification is enabled, it applies your content rules. Forage recognises what documents contain using transparent rules built from phrases, patterns, checksum validation and proximity. Every finding keeps the words that produced it, and the same document always gives the same result. Where you ask for them, the AI assistant, inside your own deployment, can also suggest labels for the kinds of record it finds, for people to accept; nothing is labelled until a person accepts a suggestion and switches its rule on.
5. The text stays in your deployment. Forage keeps the text it reads, and its search index of that text, inside your own deployment. No document content is sent anywhere outside it, with one choice of yours: if you connect Forage for Copilot, the text of the files Copilot asks for goes to Copilot, in your own Microsoft 365.
Reading SharePoint and the archive
Forage reads both halves of the estate. A file that is still in SharePoint Online is fetched from SharePoint, and Forage reads its current version. A file Squirrel has archived is read from its archive copy: Forage opens the encrypted, compressed copies inside your own deployment with your own archive key, and reads the current version of each file. Both go into the same inventory and the same search.
For the archived half, your archive key has to be provided to the deployment. It is not automatic.
Keeping current
Forage keeps its picture of the estate current by asking Squirrel what was added, changed or deleted.
When a file is reported as changed, Forage fetches it and compares its fingerprint with the one it recorded, and reads it again only if the content really changed. A property or label change moves a file's modified date as readily as new content does, so a change is treated as a trigger to look, never as a conclusion that the content differs.
Forage picks up changes on a regular sweep rather than instantly, and it can be no more current than Squirrel's own record.
Accounting for everything
Every file in the estate is accounted for, whether read, excluded by type or by policy, or failed with a recorded reason. Coverage is reported against the files in the sites you include, with every SharePoint site shown beside it for reference, rather than against what was convenient to read.
That is the point of the Coverage and Exceptions pages: what was not read is visible, with the reason, rather than quietly missing.
See product features for how each feature behaves.
Questions go to sales@smikar.com.